The backbone of all asynchronous JavaScript operations is the event loop. So you need to know the event loop to understand how asynchronous JavaScript works.
Here, I recommend you watch a JSConf talk by Philips Roberts and another by Jake Archibald.
- Philips Roberts talks about a basic event loop and how it works
- Jake Archibald goes deeper into Tasks and Microtasks and how they interact with the Event Loop.
In this lesson, I’m going to combine what I learned from both talks into a coherent explanation that helps you understand how the entire event loop works.
The Event Loop
There are four layers in the Event Loop:
- The Call Stack
- Web and Node APIs
- The Task Queue (or Macrotask Queue)
- The Microtask Queue
The Call Stack
The Call Stack is where we run JavaScript code. Each part that needs to be evaluated goes into the call stack when it’s read by JavaScript. When the evaluation is complete, it is removed from the Call stack.
Simple Example
console.log('one')console.log('two')Here’s what happens in this simple example:
console.log('one')will be added to the call stack.- JavaScript will run
console.log('one')immediately. console.log('one')is removed from the call stack since it is complete now.- Repeat the three steps above for
console.log('two')
The console.log statement shows up at the bottom of this image because the Call Stack works in a LIFO (Last-in, First-out) way.
Complex Example
In a complex example, we have a function called runProgram that will run another function, sayHello.
function runProgram() {  console.log('start')  sayHello()  console.log('end')}
function sayHello() {  console.log('hello')}
runProgram()
I’m going to explain what happens through videos for this lesson, so please have your sound turned on!
Web and Node APIs
Functions that provide you with asynchronous behaviour are usually not built into JavaScript directly. They’re built into browsers or Node instead.
Depending on where you use them, you call them Web or Node API respectively.
- In browsers: Web API
- In Node: Node API
In case you were wondering, Node is backend JavaScript. We’ll talk about Node later as it’s necessary for most Rest API requests.
setTimeout is an example of such a function. Let’s see how setTimeout interacts with the call stack.
setTimeout(callback, 3000)Here’s what will happen:
setTimeoutappears in the call stacksetTimeoutis removed from the call stack since it’s done- 3 seconds later, the callback appears in the call stack.
How does callback magically appear in the call stack after 3 seconds?
Well, functions like addEventListener and setTimeout rely on the browser’s environment to keep of track events and timers.
We don’t know how they work because we can’t access the browser’s internals. (Ditto for Node if you’re in a Node environment).
One possible theory is the browser spins up multiple threads — one for each asynchronous action — to keep track of the events going on. I’m not sure whether this is the truth because I haven’t found evidence to prove or disprove this hypothesis.
The best thing we can do is treat the Web (or Node) APIs like black boxes that magically know when it is appropriate to call the callback.
When the time is appropriate these black boxes add the callback back into the call stack as a Task or a Microtask. Whether the callback gets added to the Task Queue or the Microtask Queue depends on the API used.
For example:
setTimeoutadds the callback into a Task Queue- A promise adds the callback into a Microtask Queue
- Mutation Observer adds the callback into a Microtask Queue
The best to check if the API uses a Task or Microtask is to check the specifications.
Task Queue and Microtask Queue
JavaScript has a Task queue and a Microtask Queue.
These queues are similar to an actual queue in real life. They use a FIFO (First-in, First-out) structure, which means the callback that comes into the queue first will be handled first.
- When an API detects it should fire a callback, the callback gets added to the respective queues.
- When the call stack is empty, JavaScript will check the queues and invoke the callback.
Let’s keep things simple by talking about the Task queue first.
setTimeout(callback, 3000)Clearing the Call Stack comes first.
JavaScript prioritizes clearing the call stack before getting any tasks from the queues. To prove this, we can run an expensive operation that takes longer than the amount of time we set in setTimeout.
// 1 Second TimeoutsetTimeout(_ => {  console.log('Callback')}, 1000)
// This takes about 3 seconds on my computerfor (let index = 0; index < 30000; index++) { console.log(index)}Notice the callback log statement doesn’t appear in the middle of the loop.
This shows that JavaScript prioritizes clearing the call stack first as the loop is still in the call stack at that point. It doesn’t let any task in the queue disrupt the work it’s doing. You can think of it like a focused worker who refuses to get distracted.
Microtasks Queue — the priority queue
Disneyland has two queues for every ride — a priority queue and a normal queue. The same concept applies to the call stack as well.
- The priority queue is the Microtask queue
- The normal queue is the Task queue
JavaScript will clear all tasks in the Microtask queue before it clears any task in the Task Queue. We can prove this by creating a promise and setTimeout within the same code.
// Resolves immediatelysetTimeout(_ => {  console.log('Timeout')}, 0)
// Promise also resolves immediatelyPromise.resolve().then(_ => {  console.log('Promise')})
// This proves the call stack must completed and cleared before Microtasks and Tasks can be called.console.log('Last')This explanation matches the console.log statements we see in the console.
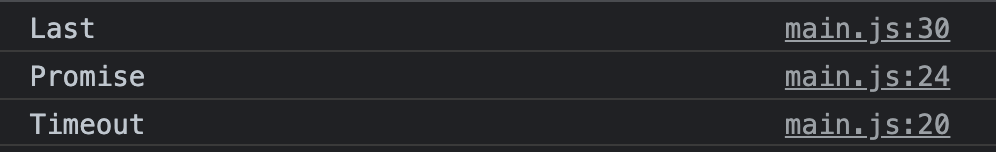
In the event that a Microtask triggers another Microtask, the new Microtask must be completed before JavaScript looks at the Task queue. We can see this in action with the following code:
// Resolves immediatelysetTimeout(_ => {  console.log('Timeout')}, 0)
Promise.resolve()  // First Microtask  .then(_ => {    console.log('Promise')  })  // Second Microtask  .then(_ => {    console.log('Promise 2')  })
console.log('Last')The console.log statements agree with the above explanation as well.
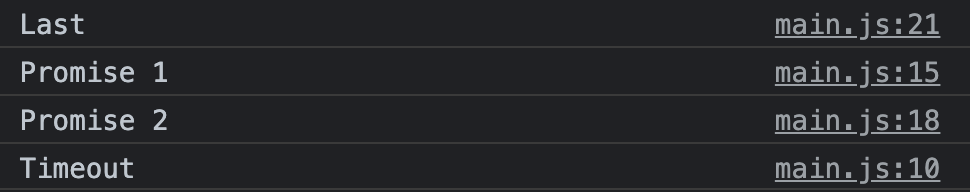
A 0ms callback doesn’t trigger immediately
You can deduce from the above example a callback of 0ms doesn’t mean the callback will be triggered immediately. The callback still needs to wait for its turn.
Further Reading
Welcome! Unfortunately, you don’t have access to this lesson. To get access, please purchase the course or enroll in Magical Dev School.
Unlock this lesson